

Google is taking another run at SerpApi after a federal judge dismissed its original lawsuit against the search-results scraping company. An amended complaint alleges that SerpApi circumvented Google’s anti-bot protections to collect and resell licensed material appearing within search results. Judge Yvonne Gonzalez Rogers previously ruled that Google could not pursue its Digital Millennium Copyright Act claims for much of the material displayed on its results pages. Google generally does not own that underlying content. The court left room for a narrower case involving material Google licenses from third parties, provided those owners authorized Google to restrict access. Google’s revised filing attempts to meet that requirement. It says licensing partners expressly asked the company to prevent unauthorized extraction of their content. Google specifically points to Reddit, alleging that its agreement does not permit third parties to extract and independently commercialize licensed Reddit material. Google also claims SerpApi bypassed SearchGuard, its system for distinguishing automated requests from human searches. SerpApi maintains that it collects information already visible to ordinary users and says it remains confident in its defense. The revised case narrows the central question. Google may have difficulty using copyright law to protect an entire search-results page, but it could have a stronger claim when scraping captures licensed content whose owners expressly requested access restrictions. Read the report from Yahoo Finance and follow the filings in Google LLC v. SerpApi LLC.
Google and Reddit vs SERPAPI Saga
- In a Win for SEOs and Webmasters, Googles’ SERPAPI “Scraping” Lawsuit Tossed
- SerpApi Responds to Google With Motion to Dismiss
- The Google Monopoly Takes Legal Aim at SerpApi
- Reddit’s DMCA Case Against Scrapers Survives, Despite Google’s Earlier Loss
- We Have A New Chapter in the Saga of OpenAI Using Google SERPs?
- Media Post
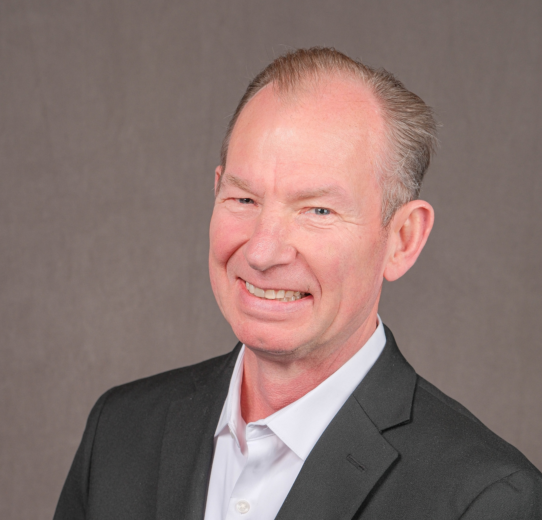
As the CEO and founder of Pubcon and WebmasterWorld., Brett Tabke has been instrumental in shaping the landscape of online marketing and search engine optimization. His journey in the computer industry has spanned over three decades and has made him a pioneering force behind digital evolution. Full Bio
Visit Pubcon.com